Inference at your site – instead of an hourly cloud GPU bill
We run the models on your NVIDIA DGX device: predictions happen at your location, with no data leaving the building and no bill that grows with every question.
-
 Models run at your location
-
No cloud costs per hour / per request
-
The NIM environment for running models
What we deploy
When local inference pays off
Local deployment is worth considering for steady request volumes or data that requires local processing. We compare hardware, software, power and maintenance costs with the cloud option.
01
A steady request volume
If the model runs every day for multiple users or processes, the monthly cloud bill grows – your own device has a fixed device price, not a per-request tariff.
02
Data that does not travel
The content of requests and answers stays in your network – important for internal documents, client data and internal regulations.
03
No waiting for quotas
The capacity is yours: no provider limits, no waiting for free instances in some region.
04
The NIM environment
Models run from the NIM environment – standardized, with the option to swap models without rebuilding the platform.
On which hardware
Three variants – by team and model size
We size by the model you want to run and the number of requests per day.
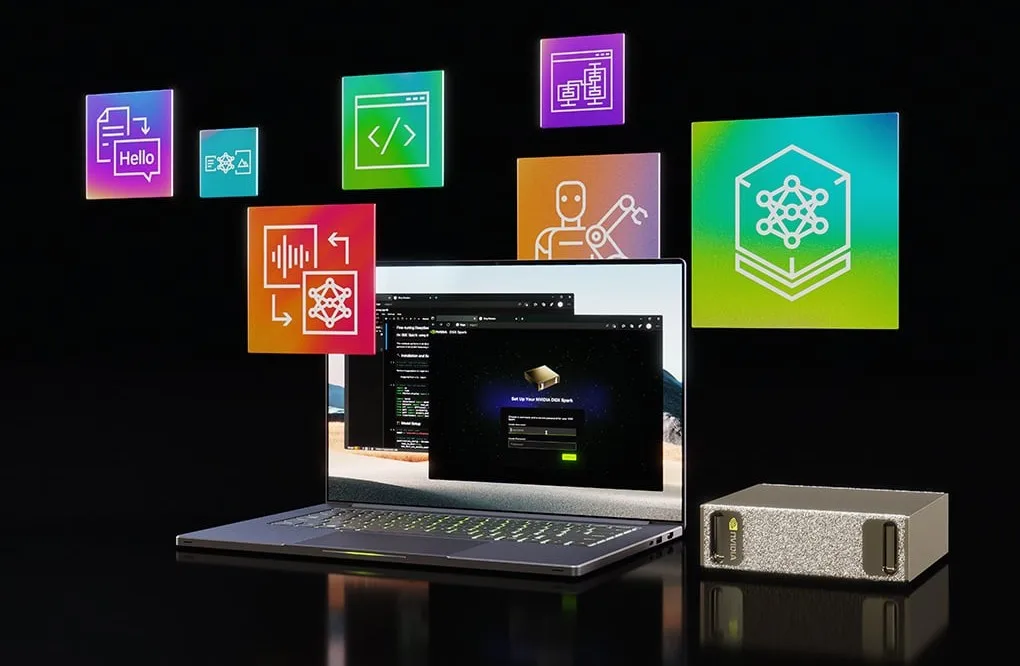
NVIDIA DGX Spark
A pilot and 1–2 users: a compact deskside device running from a regular outlet.
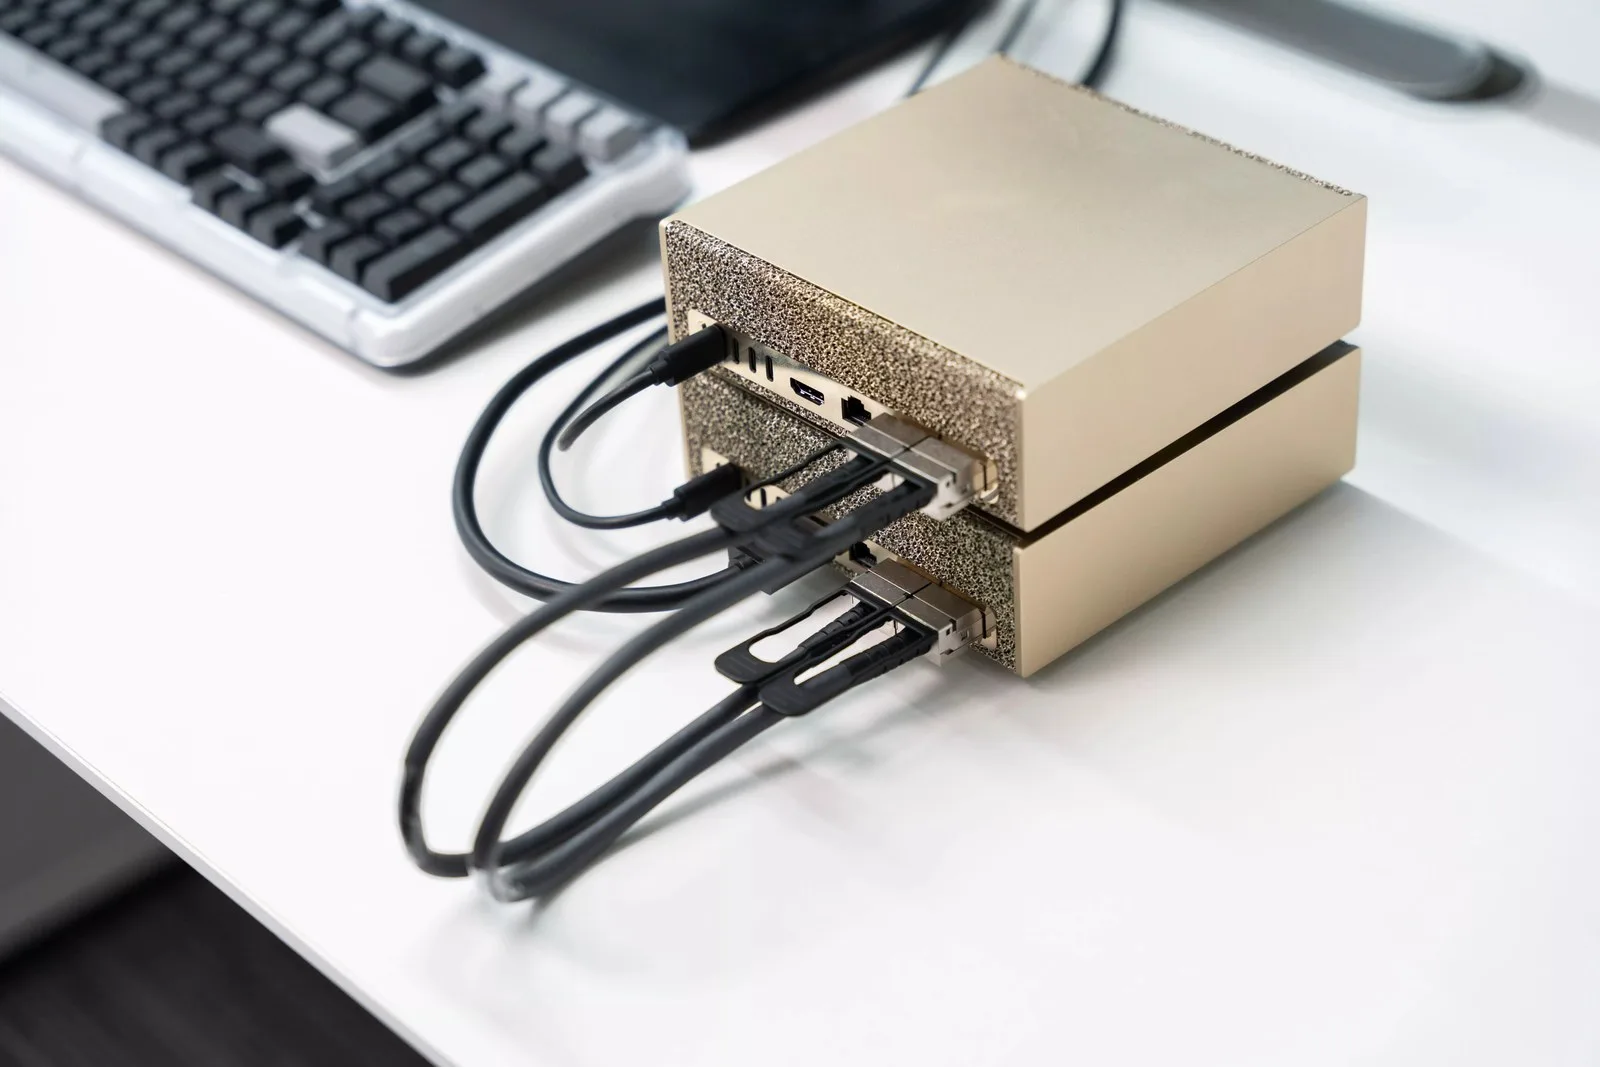
2× DGX Spark
A compact fleet for bigger jobs: two linked devices working together.
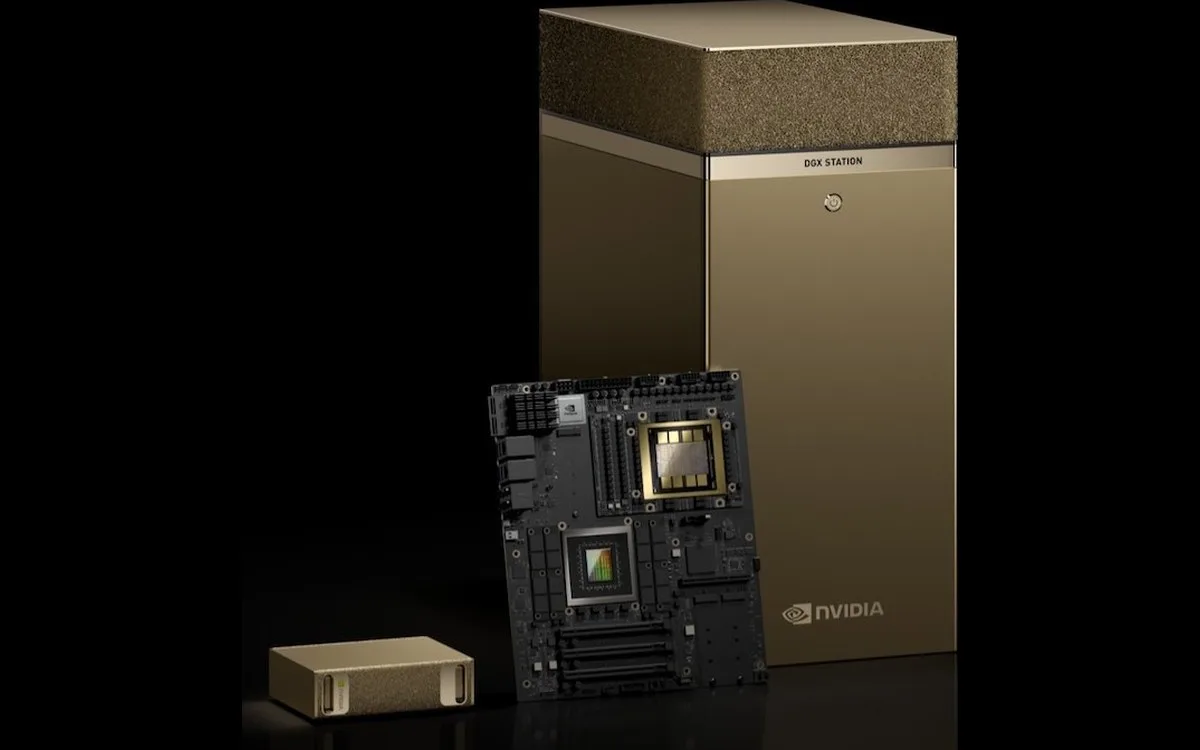
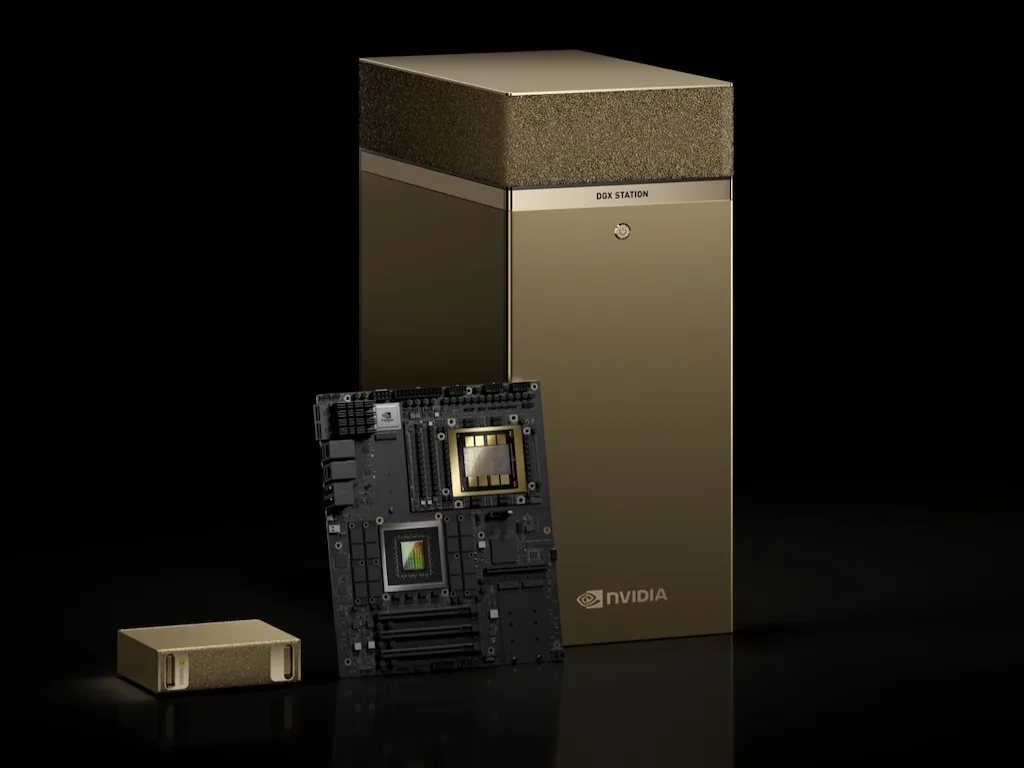
NVIDIA DGX Station
A team and larger models: MIG splits the GPU across users, up to 748 GB of coherent memory.
We will not promise throughput “out of thin air”: capacity is confirmed with a test on the concrete model, before handover.
What is in the delivery
From order to a working system
- Delivery of the NVIDIA DGX device to your location (all of Serbia)
- Installation of DGX OS, CUDA and the NIM environment – at your request
- Running the selected models and a request test on your examples
- Access from the internal network and IT team training – at your request
- Warranty service through us – RMA with the manufacturer
After commissioning, the models and access are managed by your IT team – we stay with the equipment through warranty service.
Request local inference
Tell us which model you are considering and how many requests per day you expect – we will propose a device and confirm the capacity with a test.


FAQ
Frequently asked questions
NVIDIA
Local AI solutions
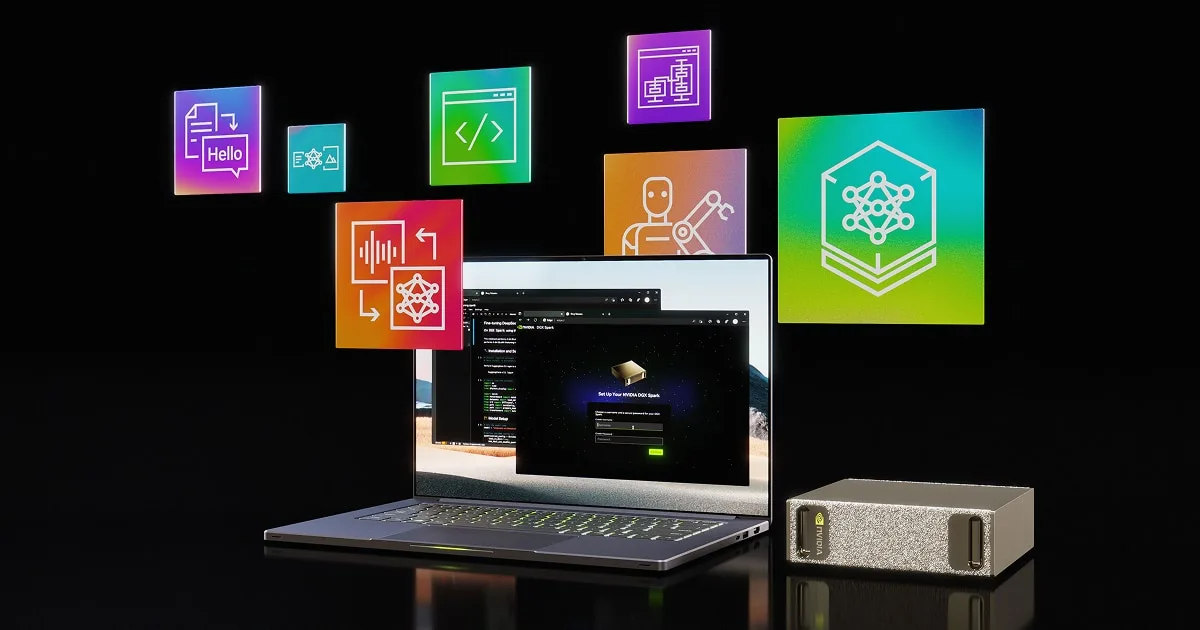
NVIDIA DGX Spark
A compact AI workstation for the desk: GB10 Grace Blackwell, 128 GB unified memory, ~240 W from a regular outlet.
NVIDIA DGX Station
A deskside AI supercomputer for large models and teams: GB300 Grace Blackwell Ultra, up to 748 GB of coherent memory.
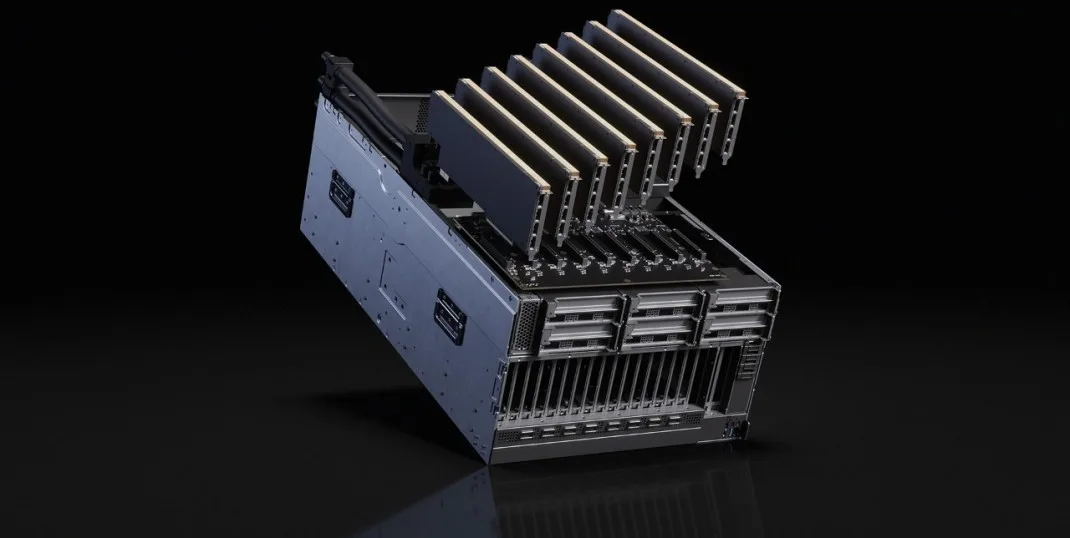
NVIDIA RTX PRO Server
A rack GPU server: up to 8× RTX PRO 6000/4500 Server Edition, vGPU/MIG sharing for multiple users at once.
Not sure which system fits?
Describe the scenario and the number of users – we will propose the device and configuration, with delivery and commissioning.