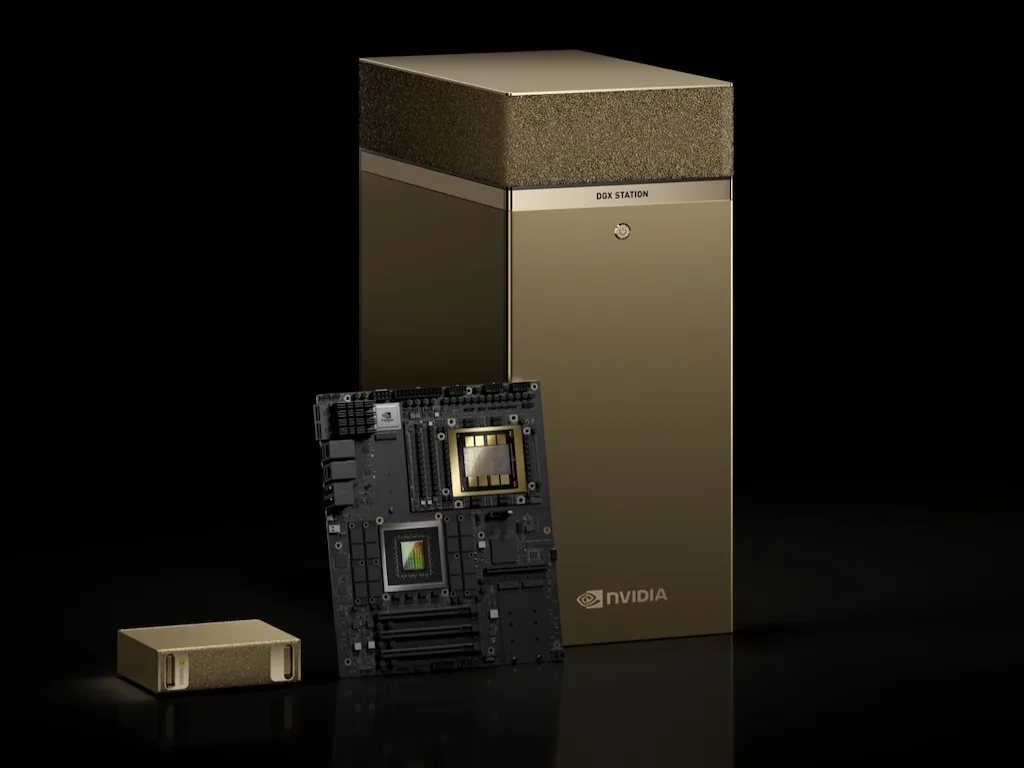
NVIDIA DGX Station – an AI supercomputer next to the desk
A deskside system on the GB300 Grace Blackwell Ultra for large models and the whole team: up to 748 GB of coherent memory, MIG for parallel work – all in a tower next to the desk, no server room. Before delivery we check the power, cooling and network at the site.
-
 GB300 Grace Blackwell Ultra
-
Up to 748 GB of coherent memory
-
Tower format, MIG for the team
NVIDIA DGX Station
The specification, stated exactly, with no double meaning
| Superchip | NVIDIA GB300 Grace Blackwell Ultra – a 72-core Grace CPU and Blackwell Ultra GPU over NVLink-C2C (900 GB/s) |
|---|---|
| Memory | Up to 748 GB of coherent memory: 252 GB HBM3e (7.1 TB/s) beside the GPU + 496 GB LPDDR5X beside the CPU |
| Performance | Up to ~20 PFLOPS AI (FP4) per NVIDIA figures |
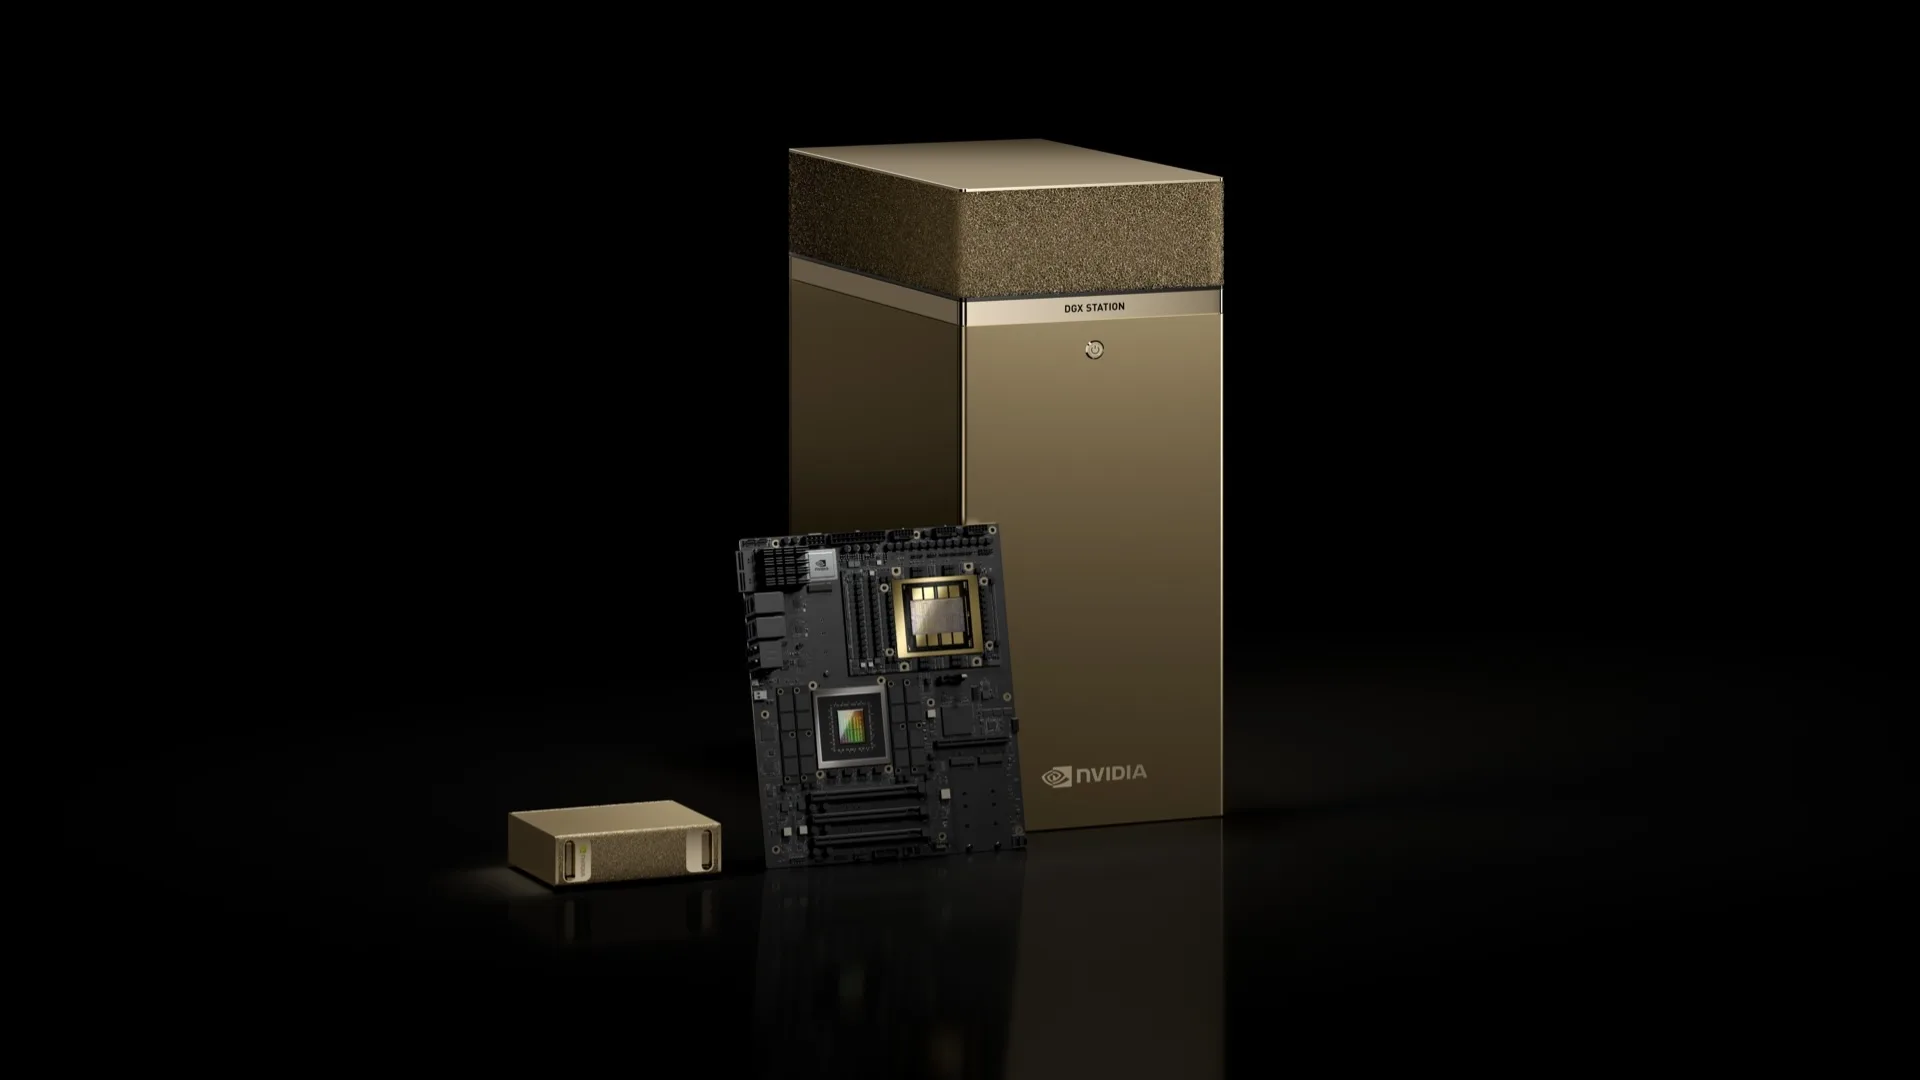
| Format | Tower / deskside – next to the desk, no server room or rack cabinet |
| Power | Up to ~1600 W – before delivery we always check the power, cooling and network at the site |
| Resource sharing | MIG – the GPU splits into up to 7 isolated instances for multiple concurrent users |
| Networking | ConnectX-8 SuperNIC (up to 800 Gb/s), 2× QSFP112 at 400 Gb/s – for the network or a second Station |
| Storage | 4× M.2 NVMe (Gen 5) |
| Expansion | Optional: an additional RTX PRO GPU (6000 / 6000 Max-Q / 4000 SFF / 2000 Blackwell) |
| Software | DGX OS (Ubuntu) or NVIDIA DGX Station for Windows – the choice is confirmed in the quote |
How it works
From the wall outlet to the model’s answer
The Station needs no rack or server room: power on a dedicated circuit, office-class cooling and one tower – everything else is software.
01
The model and data stay with you
The Station ships with Ubuntu and the NVIDIA AI tools (CUDA-X, NIM): the model loads locally – queries and data do not go to a public cloud.
02
The whole model in coherent memory
748 GB of one address space: 252 GB HBM3e (7.1 TB/s) beside the GPU and 496 GB LPDDR5X beside the CPU, linked by NVLink-C2C at 900 GB/s.
03
Grace CPU + Blackwell Ultra GPU
A 72-core Grace CPU and a Blackwell Ultra GPU with up to 20 PFLOPS FP4 of performance – a class of work that used to need a rack cabinet.
04
MIG – one device, the whole team
The GPU splits into up to 7 isolated instances: each team member gets their own share of resources, with no contention and no waiting.
Models
Which models run on the DGX Station
NVIDIA lists models up to a trillion (1T) parameters running on the Station – and the limits grow by linking two Stations.
1T
parameters – inference
models up to a trillion parameters, per NVIDIA’s official figures for the Station (quantized)
MIG 7
isolated instances
the GPU splits into up to 7 parts – several people work on the same device at once
2×
linked Stations
Connect up to two DGX Stations over the ConnectX-8 network – resources remain distributed across the devices
NVIDIA Nemotron
Open NVIDIA models for reasoning, code and agents – the largest classes run on the Station too.
OpenAI GPT-OSS (20B / 120B)
Open OpenAI models – on the Station they run in full memory, without quantization compromises.
Meta Llama 3.x
The most widespread family: 8B for quick tasks, the large versions for serious work.
DeepSeek-R1
Reasoning models – locally, without internet, with room for long contexts.
Google Gemma 3
Lightweight models with image support – practical for everyday work.
Qwen3 · Mistral · Phi-4
Popular open families for code, documents and agentic scenarios.
These are the families NVIDIA officially highlights alongside the DGX platforms – it is not a limitation. DGX OS is a standard Linux with the NVIDIA AI stack (NIM, TensorRT-LLM, vLLM, SGLang, llama.cpp), and support for other open-source models from Hugging Face depends on model architecture, memory requirements and software compatibility. We check the specific model version and runtime for your intended use.
Station-to-station link
One Station is 748 GB. Two linked – more.
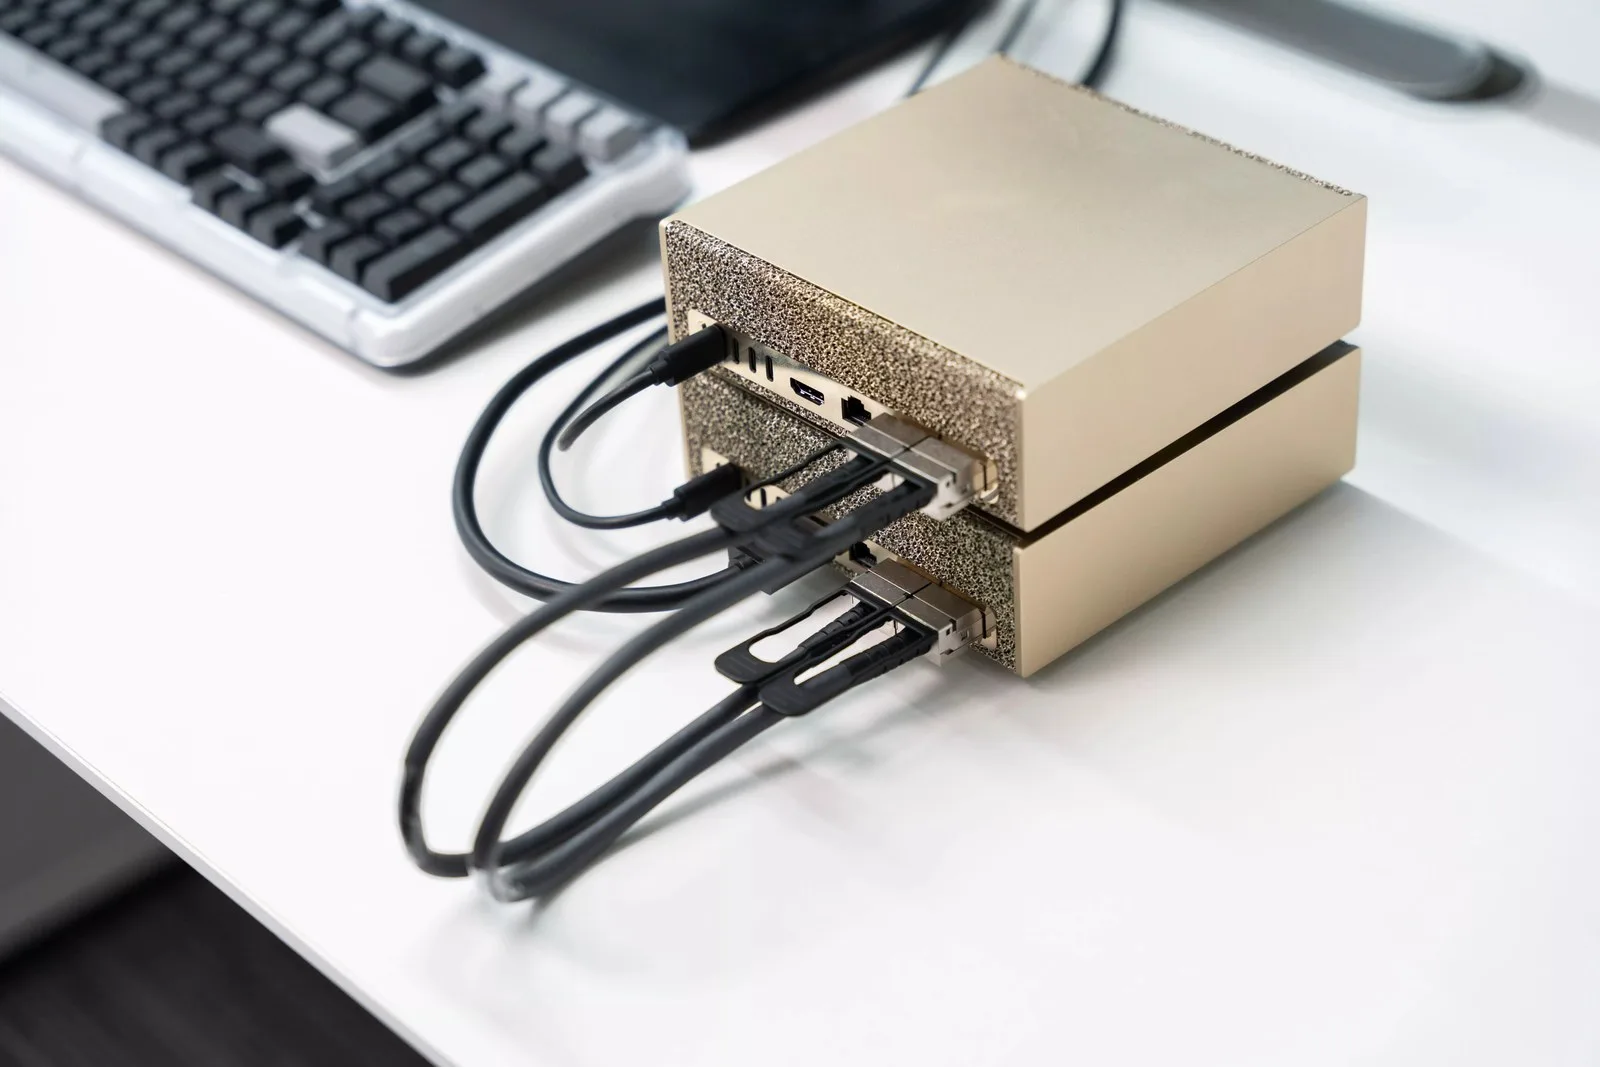
When the team and the models need more, the Station is not replaced – a second tower is added. The ConnectX-8 SuperNIC joins two Stations into a single working unit.
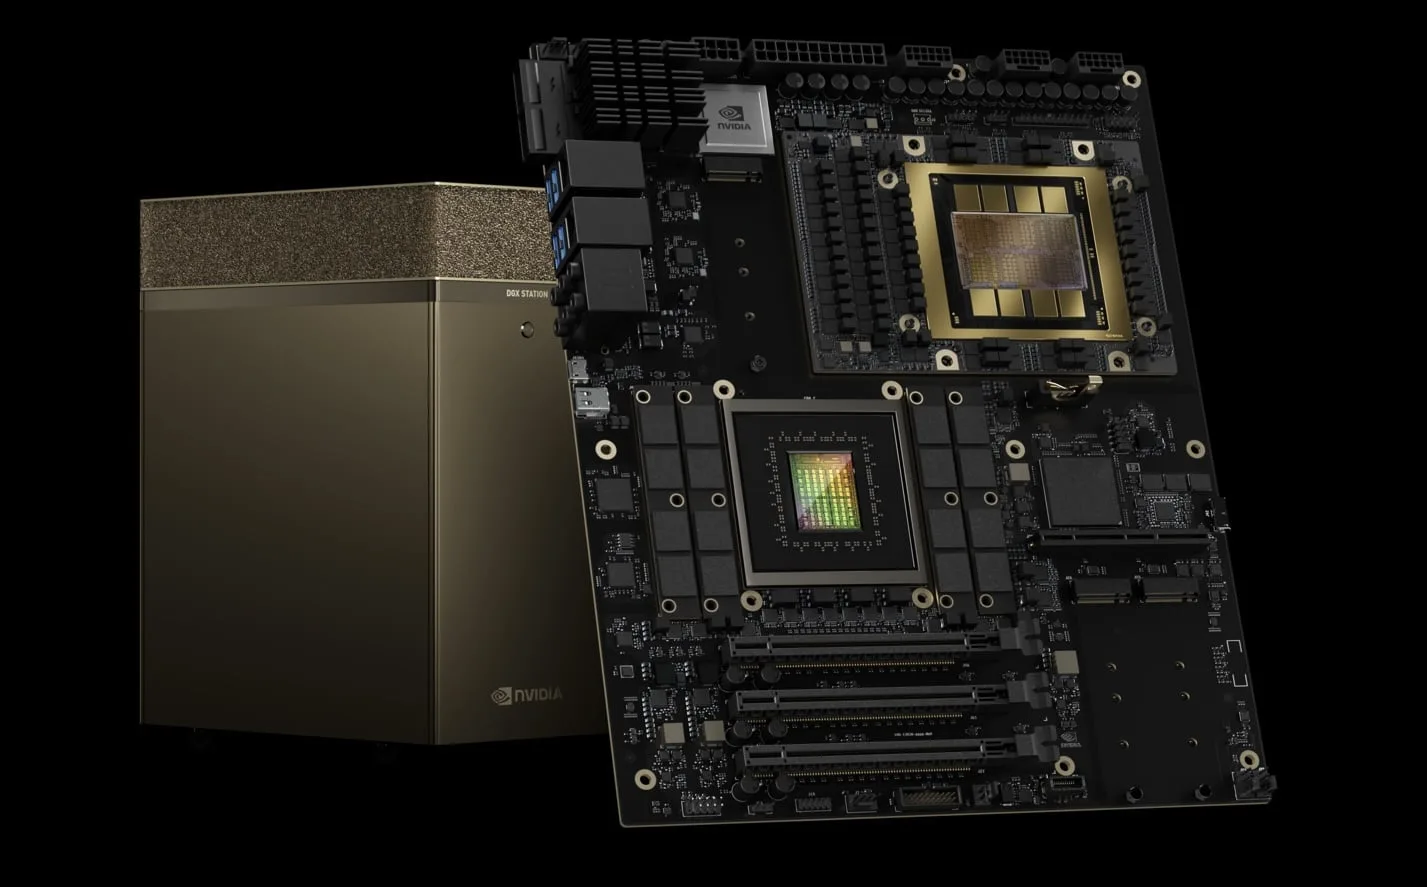
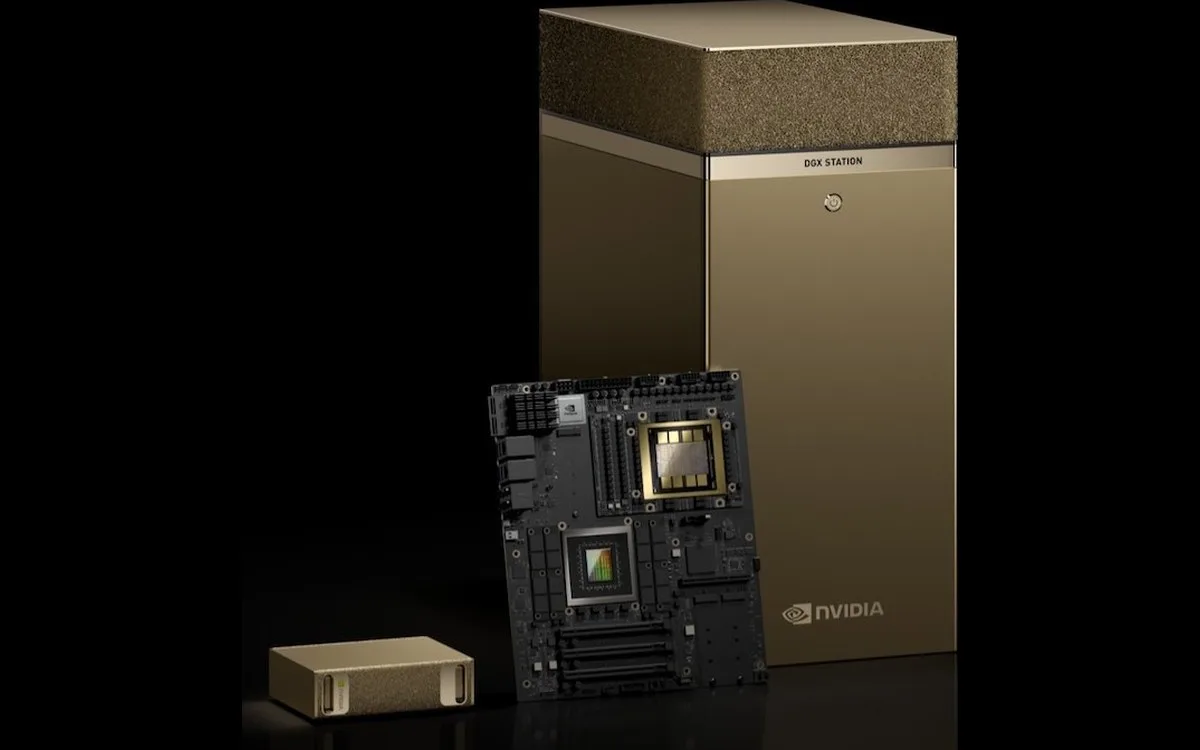
The DGX Station inside: the chassis and board with the GB300 Grace Blackwell Ultra superchip – the Grace CPU and Blackwell Ultra GPU joined by a 900 GB/s NVLink-C2C link.
How they connect
- The back of each Station carries 2× QSFP112 ports (up to 400 Gb/s each)
- The link: a QSFP112 cable port-to-port over the ConnectX-8 SuperNIC – no switch
- Total resources increase. Memory remains distributed across the devices and speedup depends on the workload
- After linking we run an NCCL check and hand over the system with a report
What is in the Station delivery
From the site audit to a working system
- 1× NVIDIA DGX Station – GB300, up to 748 GB of coherent memory
- An IT infrastructure audit before delivery – mandatory (~1600 W: power, cooling, network)
- Commissioning, MIG setup per team and IT team training – at your request
Who it is for
When the Spark is no longer enough
The Station is a step up: larger models, more people on the same device and resources shared without waiting.
A team of several people
MIG splits the GPU into isolated instances – several developers and data scientists work at once, without waiting for each other.
Large models and long contexts
When the model or context does not fit in the memory of a smaller system – 748 GB of coherent memory takes the bigger jobs.
A site without a server room
A tower next to the desk instead of a rack cabinet: server-class power, without dedicating a room and cooling infrastructure.
FAQ
Frequently asked questions
Request a DGX Station
Send an inquiry – we come back with a specification, delivery time and a site check plan (power, cooling, network) before the order.


AI deployment
What runs on a DGX
Pick a scenario – every deployment goes on the same hardware, with the same commissioning service.
Private AI in the company
An AI assistant inside the internal network – data stays at your location.
AI document search
Questions and answers over PDFs, contracts and manuals (RAG).
AI for the dev team
A work-ready DGX in your lab: DGX OS, CUDA, NIM.
Local inference
Models run at your site – instead of paying for cloud GPU by the hour.
NVIDIA
More from the NVIDIA range
NVIDIA DGX Spark
A compact AI workstation for the desk: GB10 Grace Blackwell, 128 GB unified memory, ~240 W from a regular outlet.
RTX PRO Server
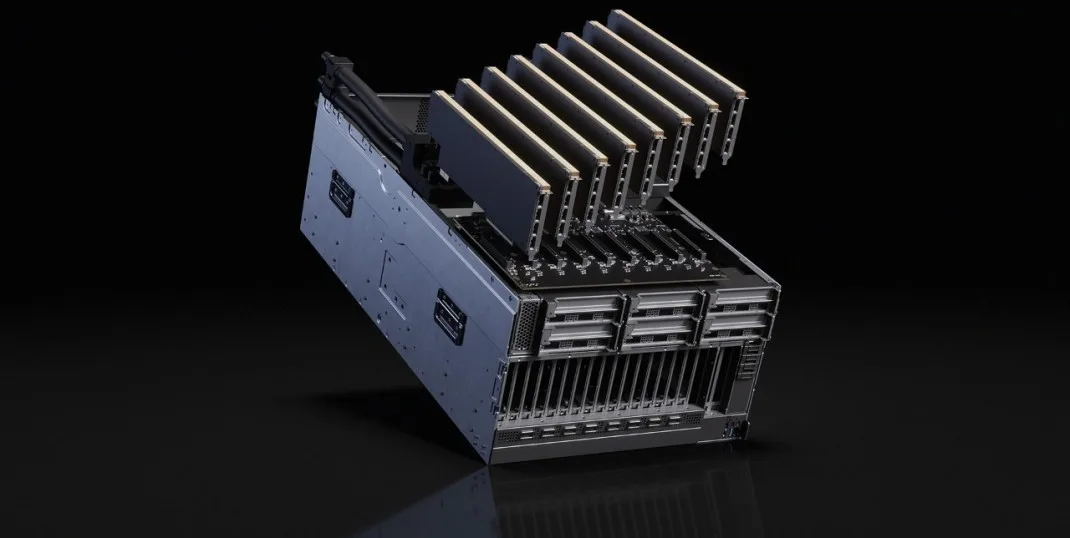
A rack GPU server: up to 8× RTX PRO Server Edition cards, vGPU/MIG sharing for multiple users.
RTX PRO Desktops
Professional desktop GPUs and workstations: up to 96 GB GDDR7 ECC, Blackwell.
RTX PRO Laptops
Mobile professional workstations on the Blackwell architecture – AI and 3D in the field.