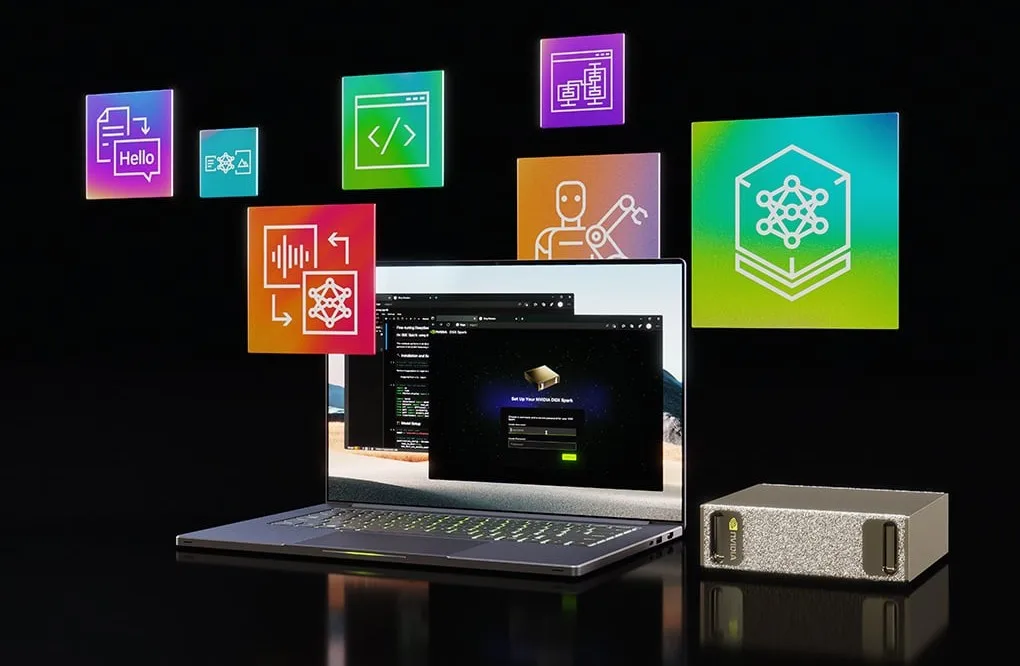
NVIDIA DGX Spark – an AI workstation for the desk
A personal AI computer on the Grace Blackwell architecture: development, fine-tuning and running models happen on your desk – quietly, from a regular office outlet, no server room. We supply the device and arrange connection and commissioning at your request.
-
 GB10 Grace Blackwell superchip
-
128 GB unified memory
-
~240 W – a regular office outlet
NVIDIA DGX Spark
Compact, with everything on one chip
| Superchip | NVIDIA GB10 Grace Blackwell – a 20-core Arm CPU and Blackwell GPU on one chip, up to 1 PFLOP FP4 |
|---|---|
| Memory | 128 GB unified LPDDR5x, 273 GB/s – available to both the CPU and the GPU |
| Storage | 4 TB NVMe M.2 with self-encryption |
| Format | A compact deskside 15×15×5 cm, ~1.2 kg – sits on the desk, needs no server room |
| Power | ~240 W: runs from a regular office outlet, no dedicated circuit |
| What it is for | Local development, fine-tuning existing models and inference – without sending data to a public cloud |
| Networking and cluster | Two QSFP ports (ConnectX-7, up to 200 Gb/s, Ethernet/RoCE) – linking devices into a cluster with a cable, no switch. Wi-Fi 7 and 10 GbE for the office network |
| Software | DGX OS (Linux) with the NVIDIA AI stack – NIM, TensorRT-LLM, playbooks from build.nvidia.com/spark |
How it works
From the wall outlet to the model’s answer
Spark needs no special infrastructure: power, network and one box – everything else is software already installed on it.
01
The model and data stay with you
The Spark runs DGX OS – Linux with the full NVIDIA AI stack. The model loads locally: queries do not go to a public cloud, and data never leaves the office.
02
The whole model in one memory
128 GB of unified LPDDR5x (273 GB/s) is shared by the GPU and CPU – the model loads in one piece, with no copying between separate memories.
03
One chip: CPU + GPU
The GB10 Grace Blackwell joins a 20-core Arm CPU and a Blackwell GPU with up to 1 PFLOP FP4 of performance – a class of work once reserved for servers, in a 15×15 cm box.
04
Power, network – done
~240 W from a regular outlet and one network cable (Wi-Fi 7 or 10 GbE). The device is quiet and allowed on the desk, not in a server room.
Models
Which models run on the DGX Spark
NVIDIA officially lists models up to 200 billion parameters running on a single Spark – and the limits grow through clustering.
200B
parameters – inference
the largest models NVIDIA lists for a single Spark (quantized)
70B
parameters – fine-tuning
the upper limit for tuning a model on one device
700B
parameters – cluster
running through a cluster of up to 4 Sparks, also quantized
NVIDIA Nemotron
Open NVIDIA models for reasoning, code and agents – the larger classes run in 4-bit quantization.
OpenAI GPT-OSS (20B / 120B)
Open OpenAI models NVIDIA specifically highlights alongside Spark – the 120B version fits on one device.
Meta Llama 3.x
The most widespread family: 8B for quick tasks, 70B for serious work on one device.
DeepSeek-R1
Reasoning models – distilled versions up to 70B run locally, without internet.
Google Gemma 3
Lightweight models with image support – practical for everyday desk work.
Qwen3 · Mistral · Phi-4
Popular open families for code, documents and agentic scenarios.
These are the families NVIDIA officially highlights alongside Spark – it is not a limitation. DGX OS is a standard Linux with the NVIDIA AI stack (NIM, TensorRT-LLM, vLLM, SGLang, llama.cpp), and support for other open-source models from Hugging Face depends on model architecture, memory requirements and software compatibility. We check the specific model version and runtime for your intended use.
Cluster and Spark Kit
One Spark is 128 GB. Two linked – more.
When the model or context no longer fits into 128 GB, the Spark is not replaced – a second device is added. Two linked Sparks run as one cluster over a 200 Gb/s ConnectX-7 network.
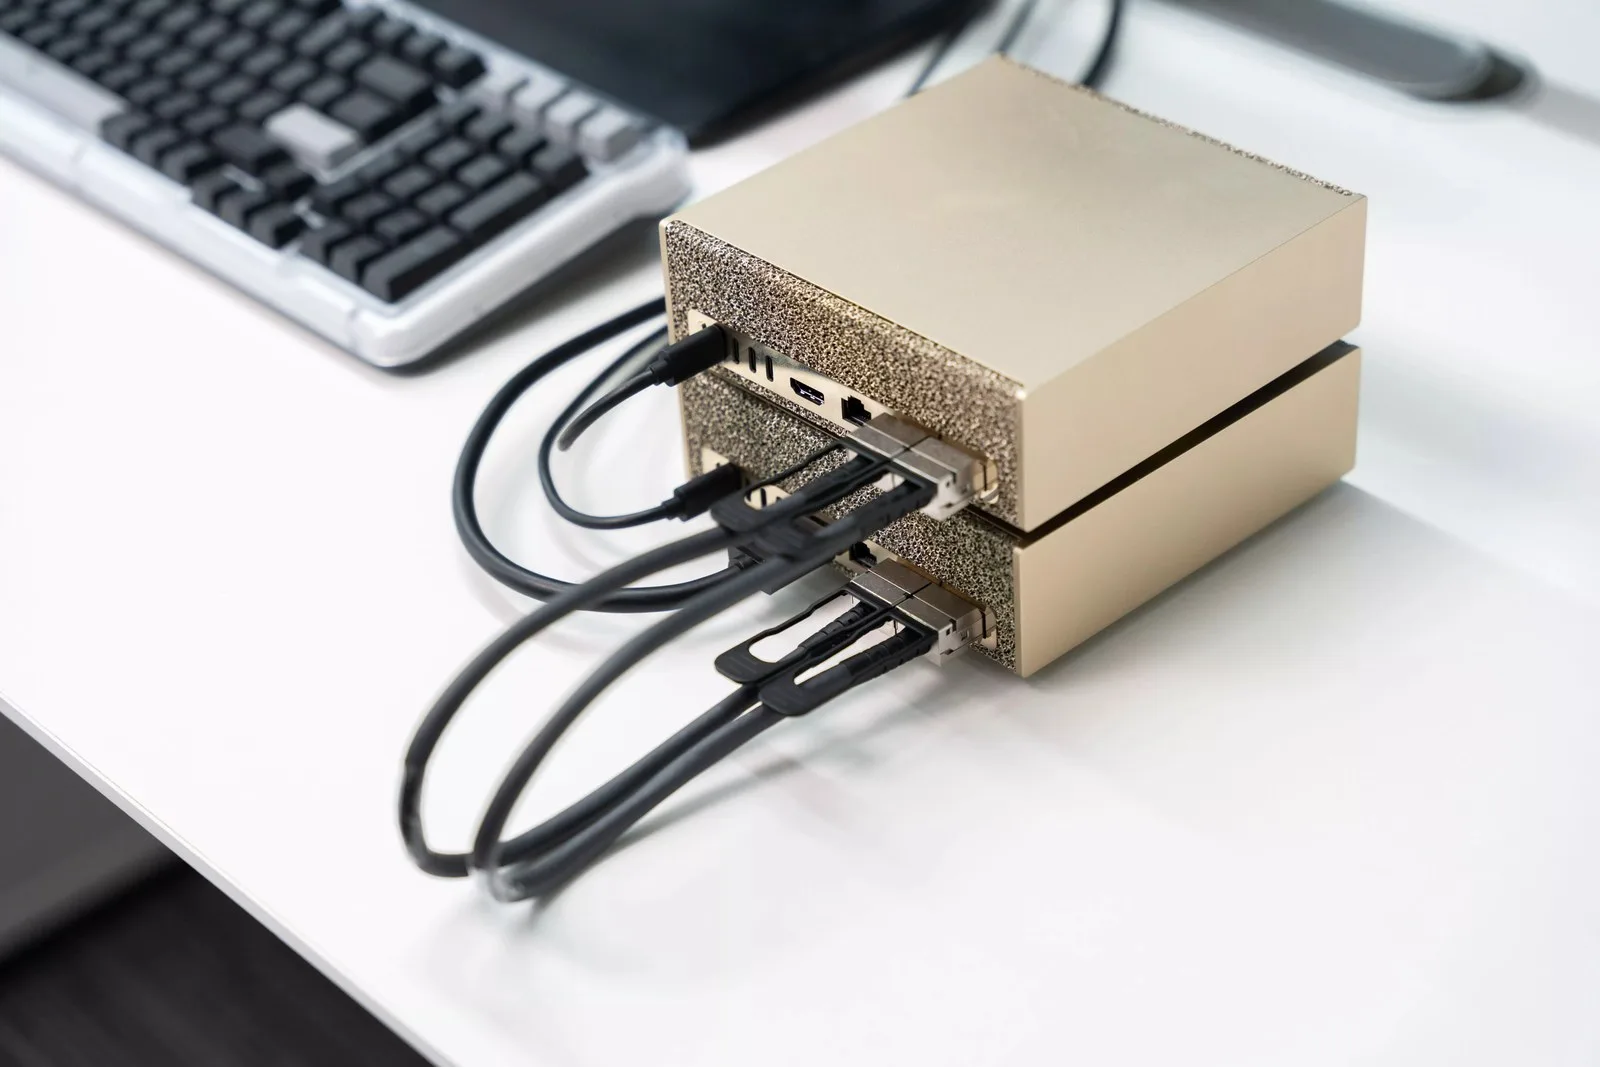
Two DGX Sparks in a cluster: a QSFP DAC cable links the ConnectX-7 ports of both devices – the link runs at up to 200 Gb/s, with no switch.
How they are linked (stacking)
- The front of every Spark carries two QSFP ports (ConnectX-7)
- Two devices sit side by side or stacked – on a desk or a cabinet
- The link: an original NVIDIA QSFP cable (DAC, 0.4 m), port-to-port – the same port number on both devices
- For two or three nodes no switch is needed. For four it is
- One cable gives a link of up to 200 Gb/s (Ethernet/RoCE). A second cable is added only by agreement, with no “double speed” promises
- After linking we run an NCCL cluster check and hand over the system with a report
What is in the Spark Kit
Everything arrives in one shipment, linked and tested
- 2× NVIDIA DGX Spark – 256 GB of memory in total across two systems. The model and software must support distributed operation
- 1× original NVIDIA QSFP stacking cable (DAC, 0.4 m)
- Delivery, linking, an NCCL link check and handover
Who it is for
Who the DGX Spark is the right choice for
Spark is the entry into the NVIDIA AI ecosystem without a server room: when the models and data need to be with you, and the team cannot wait for resources.
Pilot teams and individuals
Data scientists and developers working on models – one device covers the AI workstation.
An office without a server room
You cannot spare a room or the cooling – Spark runs from an office outlet, quietly, on the desk.
Data that does not leave
When the data must not go to a public cloud: models run locally, data stays on site.
FAQ
Frequently asked questions
Request a DGX Spark
Send an inquiry – we come back with a specification, delivery time and the terms of commissioning at your location.


AI deployment
What runs on a DGX
Pick a scenario – every deployment goes on the same hardware, with the same commissioning service.
Private AI in the company
An AI assistant inside the internal network – data stays at your location.
AI document search
Questions and answers over PDFs, contracts and manuals (RAG).
AI for the dev team
A work-ready DGX in your lab: DGX OS, CUDA, NIM.
Local inference
Models run at your site – instead of paying for cloud GPU by the hour.
NVIDIA
More from the NVIDIA range
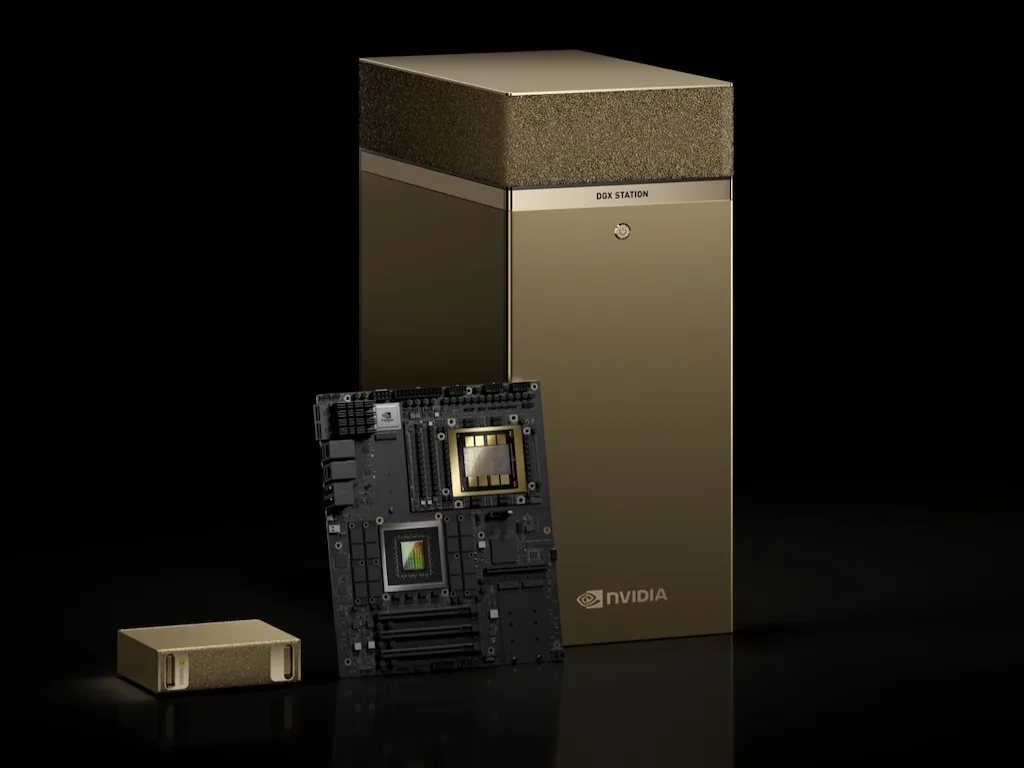
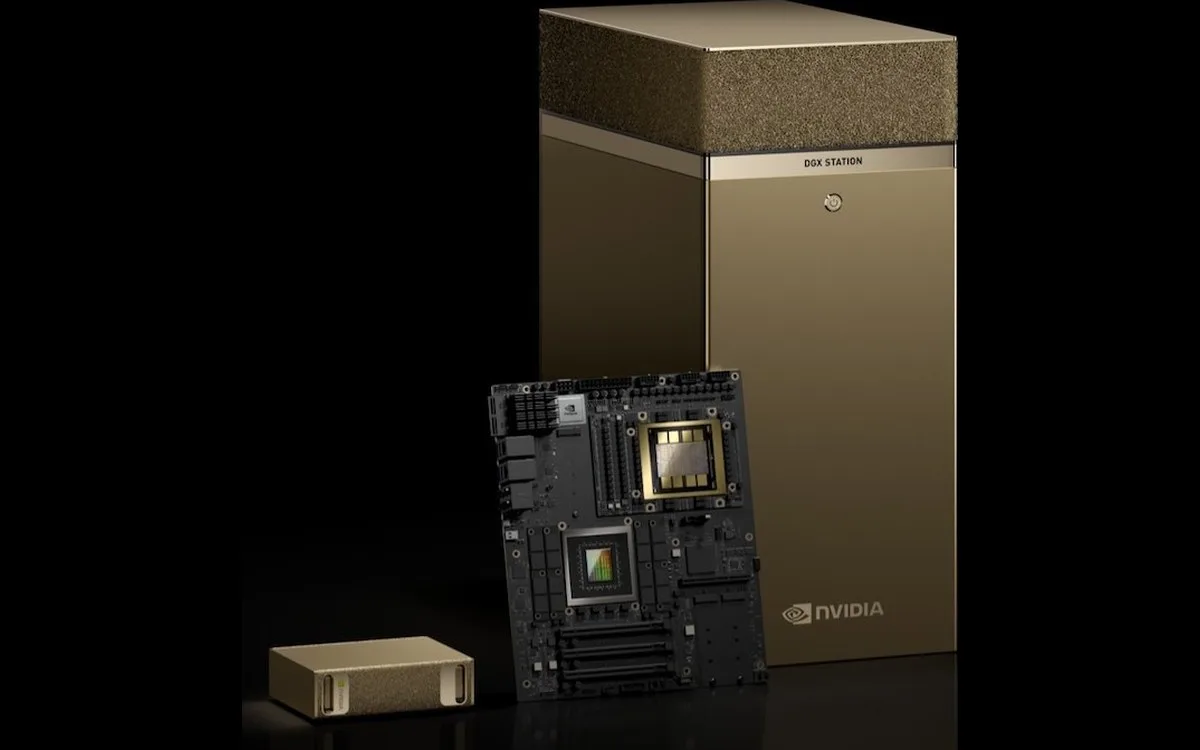
NVIDIA DGX Station
A deskside AI supercomputer for large models and teams: GB300 Grace Blackwell Ultra, up to 748 GB of coherent memory.
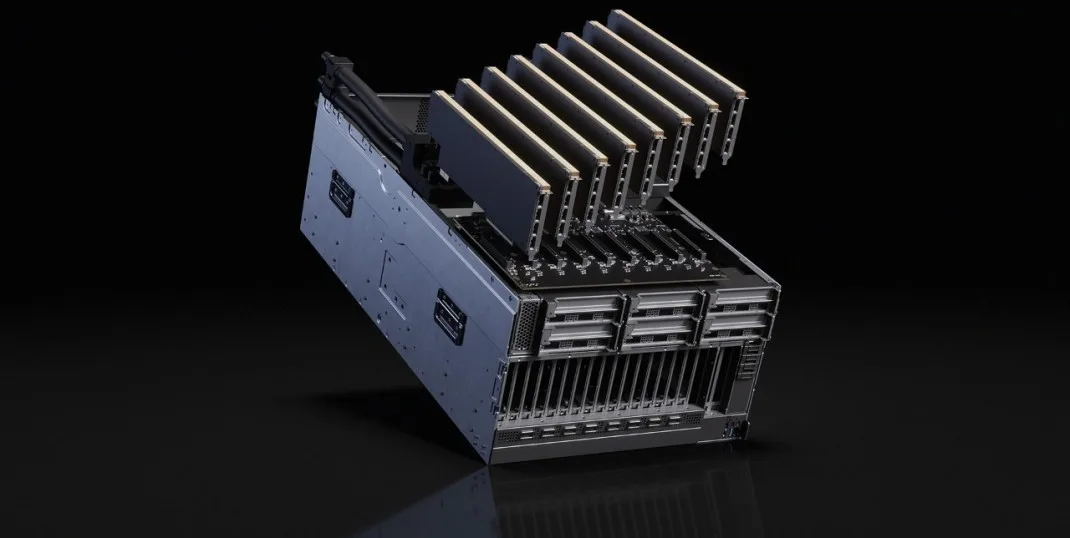
RTX PRO Server
A rack GPU server: up to 8× RTX PRO Server Edition cards, vGPU/MIG sharing for multiple users.
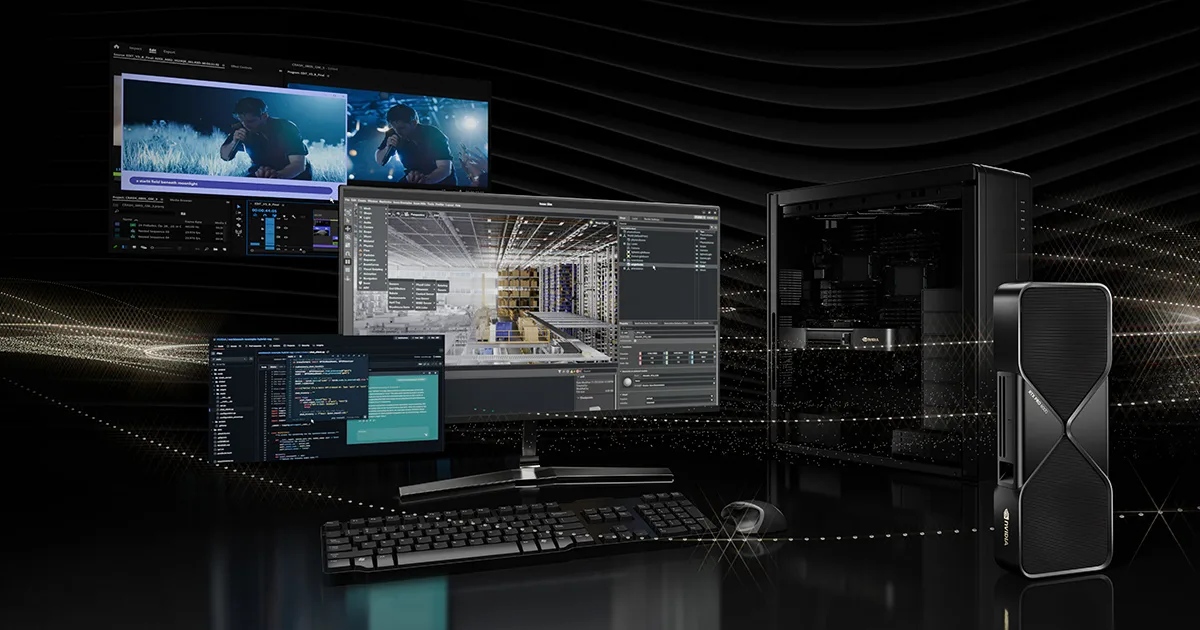
RTX PRO Desktops
Professional desktop GPUs and workstations: up to 96 GB GDDR7 ECC, Blackwell.
RTX PRO Laptops
Mobile professional workstations on the Blackwell architecture – AI and 3D in the field.